Most optimisation problems taught in computer science involve searching for the single best solution. From binary search to graph-based shortest path algorithms. We are primarily interested in the smallest cost, largest profit, or least amount of time.
Seldom do these techniques sufficiently solve real-world problems, where nuance and domain knowledge create complex trade-offs and conflicting goals. Often, improving one objective comes at the cost of sacrificing another.
The answer to these limitations can be found in nature: genetic algorithms.
Introduction to Genetic Algorithms?
Genetic Algorithms (GAs) iteratively evolve a population of candidate solutions using elements of the process of natural selection such as crossover and mutation. The GA eventually finds a single or set of optimal solutions to the complex problem.
GAs perform best at solving problems where traditional optimisation techniques are impractical or inefficient.
Why Multi-Objective Optimisation?
In many real life scenarios, objectives conflict. Maximising one objective comes with the trade-off of reducing the optimality of the other objective. For example:
- Maximising fuel efficiency may increase manufacturing cost
- Optimising machine learning parameters may increase compute time and the risk of over fitting.
Here, an algorithm which produces just one optimal solution does not make sense. The “best” solution depends on the compromise in objectives you are willing to make.
Examples of problems where GAs outperform traditional optimisation techniques:
- Solving complex multi-paremeter mathematical functions and equations
- Solving scheduling problems (e.g. maintenance, flights, exams)
- Finding optimal design configurations (e.g. motor vehicle design)
- Feature selection (e.g. optimising parameters in ML models)
- Optimising route planning in logistics and transportation.
From Single Best to Tradeoffs: NSGA-II
The aim of NSGA-II is to optimise a set of given objectives, where the objective is a specific, measurable goal that we are attempting to maximise or minimise. NSGA-II works best when objectives are conflicting.
NSGA-II is a non-dominated multi-objective sorting algorithm which adapts the general form of GAs, utilising elitism and crowding distance to return a set of Pareto-optimal solutions. I will explain these concepts in detail in the following section.
Key Concepts
Pareto Fronts
In order to define a Pareto front, we must first understand what it means to be Pareto optimal. Pareto optimality is determined by asking ourselves the question: “Do any solutions that are better in both objectives exist?”. For a solution to be Pareto optimal, there must be no way to improve one objective without worsening another.
Let’s assume we are trying to minimise one objective (Objective 1) and maximise another (Objective 2). In Figure 1, we are determining whether the blue individual is dominated. It is important to note that most visualisations of the stages of NSGA-II are in the objective space—we plot the values of the fitness function, not the values of the variables that led us to this solution. The red individual is worse in Objective 1 since we are trying to minimise this value, but performs better in Objective 2. We ask ourselves, is the blue individual better in at least one objective? The answer is yes, so we can conclude that the red individual does not dominate the blue individual.
Figure 1: Comparing selected individual with a solution better in one objective

We repeat this process for all other individuals in the population, comparing their objective values with our selected blue individual. For the sake of our understanding, Figure 2 demonstrates comparing the blue individual to a solution which is worse in both objectives.
To save time, I will reveal that our chosen individual is better than all other solutions in at least one objective, and therefore, the blue individual is said to be non-dominated and included in the Pareto front (Figure 3). The set of all Pareto optimal solutions forms a Pareto Front.
To determine the first Pareto front (Front 0) we explore the whole objective space, repeating this process iteratively until all Pareto optimal solutions are found. Figure 4 shows Front 0, the set of solutions which are not dominated by another other individual.
Figure 2: Comparing an individual with a solution worse in all objectives

Figure 3: Adding an individual to the Pareto front

Figure 4: Pareto front 0, the set of all optimal solutions

Non-Dominated Storing
Non-dominated sorting is a method of ranking sets of solutions. Subsequent fronts (i.e. the second best set of solutions) can be determined by removing the previous front’s solutions and finding the next set of non-dominated solutions. The sets of solutions are sorted based on their non-dominance. For example, Figure 5 shows all solutions in Front 0 are dominated by exactly 0 other solutions. All solutions in Front 1 are only dominated by solutions in Front 0, and are therefore categorised as the second best set of solutions, and so on.
Figure 5: Non-dominated sorting of fronts

Elitism
A strategy in genetic algorithms where the best one or more solutions in each generation are inserted into the next, without undergoing any change. In the context of NSGA-II, any non-dominated solution is considered elite and therefore injected into the replacement population for the next iteration of the algorithm.
This prevents the loss of the ‘good’ solutions which we have found so far.
Crowding Distance
Crowding distance is a measure to determine the density of solutions in a specific region of the pareto front. If individuals belong to the same front, the algorithm will prefer the solution with the greater crowding distance, as this solution is located in a less crowded region. This mechanism prevents clustering and encourages the population to spread across the entire Pareto front. Figure 6 shows two individuals, A and B, within the same front. If these two individuals were competing for a place in the population, individual B would be preferred as it in a less dense region of solutions.
Figure 6: Spread of solutions in the Objective space

How Does NSGA-II Work?
Generally, GAs are iterations of seven distinct steps:
- Initialise a population of candidate solutions
- Evaluate the fitness of each solution against a set of objectives
- Ranks solutions using non-dominated sorting
- Select parents via some predefined selection method
- Apply crossover and mutation
- Form a new population using elitism and crowding distance
- Verify if termination criteria has been met.
The result is a set of optimum choices.
Example using Pymoo
To explore NSGA-II, I’m using Pymoo, an open source framework for multi-objective optimisation in Python with visualisation and decision making capabilities.
Using Pymoo alongside NumPy, Pandas, and Plotly we can perform a complete exploration and visualisation of NSGA-II with the flexibility to define our own objectives, evolve a population of solutions and visualise the Pareto front in an interactive plot.
For those following along, the companion codebase is availabe here: https://github.com/4CDA/genetic_algorithms
Problem Statement
Our task is to evolve a population of cars to produce a set of best possible car design characteristics to optimise fuel consumption, performance and cost.
For the purpose of this tutorial, I am assuming that our three objectives can be modelled as functions of the variables weight, displacement and horsepower, and have defined three proxy equations.
Note: this example is based on the classic Auto MPG dataset, a commonly used collection of cars and their characteristics from the 1970s to 1980s. Since I have used proxy equations, we need not implement the algorithm with actual data however, a real life implementation would use linear regression to determine the most accurate models of fuel, performance and cost, and use the lower and upper bounds for each explanatory variable as inputs into the NSGA-II model.
Implementing NSGA-II with Pymoo
The NSGA-II algorithm is simple to implement using Pymoo’s relevant functions. There are built in visualisation and decision making capabilities however, Plotly express has been used to create more customisable and interactive 3D plots.
Basic Python and object orientated programming concepts have been assumed. I have also assumed knowledge of visualising data in Python however, if you require a refresher or are new to the data visualisation world, Geeks for Geeks is a great beginner resource, and Plotly has very thorough documentation for those with more experience.
Defining a Problem in Pymoo
Displacement and Horsepower are discrete valued variables, to ensure the algorithm treats them as such, we must define discrete values to replicate real life interpretations of these values.
In the _evaluate function we define decision variables, displacement, weight and horsepower. NSGA-II naturally minimises the objective functions defined just below the above. To ensure our performance function is maximised, we multiply the function by -1.
# define discrete displacement and horsepower values to replicate real life interpretations of these values
DISPLACEMENT_BANDS = np.array([70, 100, 140, 200, 300, 400])
HORSEPOWER_BANDS = np.array([50, 70, 90, 110, 150, 200, 250])

class AutoMPGProblem(ElementwiseProblem):
    def __init__(self):
        super().__init__(
            n_var = 3,
            n_obj = 3,
            xl = np.array([0, 1500, 0]), # lower bounds
            xu = np.array([
                len(DISPLACEMENT_BANDS) - 1,
                5000,
                len(HORSEPOWER_BANDS) - 1
            ]),
            vtype = int  # specify the variables are discrete integers
        )

    def _evaluate(self, x, out, *args, **kwargs):
        disp_idx, weight, hp_idx = x.astype(int)

        displacement = DISPLACEMENT_BANDS[disp_idx]
        horsepower = HORSEPOWER_BANDS[hp_idx]

        # define proxy equations for objectives
        fuel = 0.003 * weight + 0.04 * displacement + 0.02 * horsepower
        performance = horsepower / weight
        cost = 0.001 * displacement**2 + 0.002 * horsepower**2

        out["F"] = [fuel, -performance, cost]
Running NSGA-II in Pymoo
To run the algorithm, we must define the population size and stopping criteria at a minimum. For more bespoke implementations of the algorithm, we can also specify the crossover and mutation operators where we will define parameters such as the probability of crossover. The default values for these operators are used, with the default crossover operator being Simulated Binary Crossover with a probability of 0.9.
# set up algorithm
car_algorithm = NSGA2(pop_size = 400)
car_problem = AutoMPGProblem()

# gather results
car_result = minimize(
    car_problem,
    car_algorithm,
    termination = ('n_gen', 100),
    save_history = True  # set to true so we can plot all generated solutions later
)
Results & Visualisation
As mentioned throughout this article, NSGA-II is efficient at allowing researchers to explore the set of “best” possible solutions. The algorithm will not produce one single “best” solution. Plots of the objective space are the most common visualisations for problems using NSGA-II as we can see the best possible values of the functions we wish to optimise.
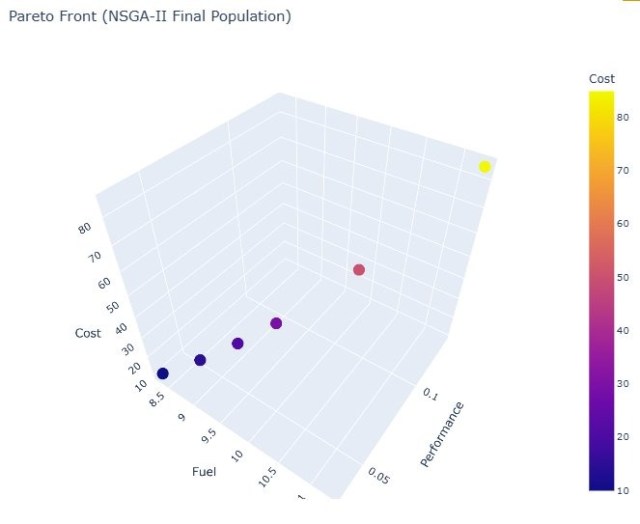
Figure 7 shows an interactive plot of the Pareto front. A tooltip with the objective values will appear when you hover over each solution. Solutions which fall in the middle of the front offer more balance trade-offs, while the extreme solutions optimise one objective more heavily.
Figure 7: Set of the best possible solutions, coloured by their cost
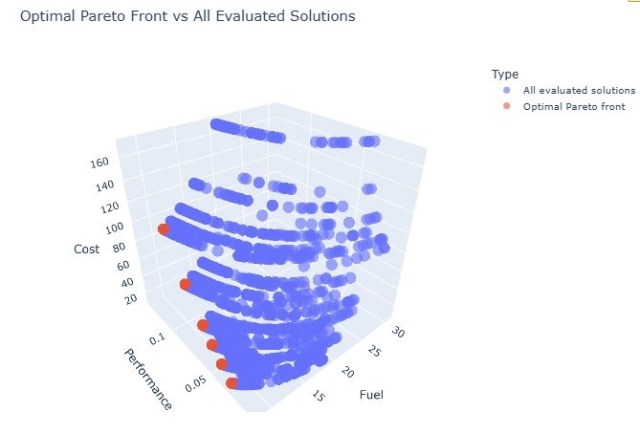
Based on the elitist principles of NSGA-II our Pareto Front should the best solutions generated throughout the algorithm. To confirm this we can plot the set of all generated solutions and colour them based on the Pareto optimality.
Figure 8 demonstrates a 3D interactive plot of this scenario and confirms our assumption of elitism.
Figure 8: 3D plot of all evaluated solutions and optimal Pareto Front
Applications of NSGA-II
The strength of genetic algorithms, and NSGA-II in particular lies in showing us a set of choices and their trade-offs, not what to choose.
NSGA-II is primarily adopted in engineering, agriculture, manufacturing, and planning problems where trade-offs are unavoidable and stakeholder priorities conflict.
Some published examples include:
- Sustainable agricultural systems that consider economic value, ecological sustainability, and management efficiency
- Maize irrigation and fertilisation schedule optimisation that balances yield performance, and resource usage
- Multi-objective route finding in a multi-node transportation network.
Limitations
Usage of NSGA-II does not come without its limitations, with cost and computation time being large factors in one deciding to seek other techniques. NSGA-II has an estimated time complexity of O(MN^2), where M is the number of objectives to be optimised, and N is the size of the population. NSGA-II works well without parameter fine tuning for small populations; however, for less trivial problems with large population sizes, parameters start to significantly influence the cost and efficiency of the algorithm.
Results are dependent on the encoded fitness functions, if these functions change or are found to be incorrect estimates of real life, the results of the algorithm become redundant. Broadly speaking, reducing complex and nuanced problems into relatively simple equations is a problem most computer simulations struggle with. Researchers are required to drastically simplify reality for the results to be understandable.
In Summary
To add to our example we could further include fitting of the objective models using linear regression, or combining different optimisation techniques to explore the solution space.
While relatively simple to implement in Python, NSGA-II has the capacity to expose nuance and complexities in real life multi-objective problems, where subject matters and stakeholder priorities are considered.
A powerful tool for solution set optimisation, the final decision ultimately remains in the hands of the subject matter expert, a key differentiator between NSGA-II and single-objective optimisation techniques. The algorithm can become expensive and complex very quickly so it is important to consider the use case and viable options before attempting to implement the algorithm.
The companion codebase can be found here: https://github.com/4CDA/genetic_algorithms
Reference
Genetic Algorithms: Nature-Inspired Optimization for Solving Complex Problems. https://medium.com/@derya.cortuk/genetic-algorithms-nature-inspired-optimization-for-solving-complex-problems-4dd893a9cb2c
Chapter 4: Selection Strategies. https://algorithmafternoon.com/books/genetic_algorithm/chapter04/
Selection Methods for Genetic Algorithms. https://www.researchgate.net/publication/259461147_Selection_Methods_for_Genetic_Algorithms
Crossover in Genetic Algorithm. https://www.geeksforgeeks.org/machine-learning/crossover-in-genetic-algorithm/
Pareto Optimality. https://www.sciencedirect.com/topics/engineering/pareto-optimality
What is Elitism. https://www.igi-global.com/dictionary/multi-objective-evolutionary-algorithms/9592
Crowding Distance. https://www.sciencedirect.com/topics/computer-science/crowding-distance
An Introduction to Genetic Algorithms, Melanie Mitchell, 1999. https://www.boente.eti.br/fuzzy/ebook-fuzzy-mitchell.pdf


